AI’s GPU Refresh Cycle Is Becoming a Stranded-Capital Problem
Key Highlights
- Proactive lifecycle planning involves designing infrastructure that accommodates hardware upgrades and facilitates easy disassembly and component reuse.
- Effective disposition strategies include asset traceability, secure sanitization, and compliance with international trade and data security regulations.
- Market timing and operational readiness are critical; continuous assessment of asset value ensures hardware is sold or repurposed at optimal moments.
- Design-for-recycling principles should be integrated into hardware architecture, emphasizing modularity and material recoverability to extend equipment lifespan.
- Organizational alignment at the executive level is essential to prevent stranded capital and maximize the return on AI hardware investments.
The AI infrastructure buildout is measured in gigawatts and successive generations of accelerators. But as operators bring new compute capacity online, a less visible question is gaining financial urgency: What happens to GPU systems when their first production assignment ends?
For hardware that remains functional but no longer meets the performance or efficiency requirements of a leading-edge AI cluster, retirement need not mean obsolescence. Equipment may be redeployed, resold, harvested for components or processed to recover materials. The outcome depends on decisions made long before a system leaves its rack.
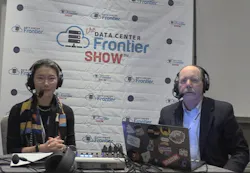
That was the central argument advanced by Linda Li, chief strategy officer of Re-Teck and its parent company, Li Tong Group, in the latest onsite installment of the DCF Show podcast, hosted by Data Center Frontier Contributing Editor Doug Black at the DCF Trends Summit 2026 in Northern Virginia. For Li, the acceleration of GPU refresh cycles is making lifecycle management a question of capital preservation, facilities design and executive governance—not merely IT asset disposition.
Plan for the Exit Before the Equipment Arrives
Li draws on more than two decades of her company’s work in reverse supply chains for consumer electronics and telecommunications equipment. Both sectors have managed rapid generational shifts without assuming that every displaced device had exhausted its useful life.
“We are dealing with a totally different organism,” she said, describing the combination of rapid accelerator iterations, rising rack power density and increasingly sophisticated thermal requirements.
The response, in her view, has two levels. The first is physical infrastructure: facilities designed to accommodate successive generations of servers without extensive reconstruction. Scalable power distribution, adaptable raceways, modular rack systems and high-capacity air and liquid cooling can create room for hardware transitions that may arrive sooner than originally expected.
The second is the network of partners and contracts around the assets. Rather than recruiting an IT asset disposition (ITAD) provider when a refresh is imminent, operators should assess processing capacity, certification, geographic reach and compliance during procurement.
Li pointed to the telecom industry's transition from 3G to 4G and 5G. In that environment, she explained, the contract to supply next-generation network equipment can also obligate the supplier to take back and decommission what is being replaced. She believes AI infrastructure purchasing should incorporate similar provisions.
“What kind of planning needs to be done and when it needs to be done” are inseparable questions, Li said. “You can't answer one without the other.”
Finding the Next Life of a GPU
The appropriate disposition pathway cannot be fixed years in advance. Li described a framework established when equipment enters service, with final decisions made at retirement as its condition, market demand and operational needs become clearer.
The first consideration is remaining capability. An accelerator that is no longer economical for frontier model training may still be useful for inference, enterprise AI or academic research. For large operators with multiple sites or classes of workload, moving the equipment internally can preserve more value than selling it—and can reduce the need for additional purchases.
That requires identifying suitable destinations and approving transfers in advance. Otherwise, reusable systems can become stranded in the organizational handoff.
The second consideration is component-level economics. Demand for an entire previous-generation server may soften even while individual GPUs, memory modules or specialized networking cards retain strong market value. Recovering those parts requires an engineering understanding of the equipment’s design and assembly, not just the ability to transport and recycle a chassis.
Harvested components can also become internal service spares. That approach may help operators maintain installed systems while reducing lead times and dependence on replacement-parts supply chains. For Li, the relevant unit of value is not always a complete server; sometimes it is the individual component that can serve another application.
Her third consideration—one she said should actually rank first—is risk. Data security, access controls, regulatory obligations and environmental rules can override an otherwise attractive commercial opportunity. The fourth is material recovery: recovering and refining valuable inputs when equipment or components cannot be economically reused.
Together, the four factors place resale and recycling within a broader decision process. The aim is not simply to maximize the price of decommissioned hardware, but to retain value without compromising security or compliance.
The Resale Market Won’t Wait
Hardware value is also time-sensitive. During the conversation, Black relayed an anecdote heard earlier at the summit about H100 accelerators attracting unusually high prices in secondary markets. Li cautioned against assuming such conditions would last.
Prices for used AI equipment, she said, can move rapidly as demand, product availability and the economics of new generations change. In some circumstances an operator might recover more than expected; in others, a delay could erase the opportunity.
That puts a premium on operational readiness. A company that waits until enough retired systems accumulate for a quarterly decommissioning project may be choosing administrative convenience over market timing. By contrast, a continuous process for assessing, clearing and routing assets allows operators to respond when there is still demand for them.
“If you let things sit,” Li warned, “you might have missed the best price window.”
Across GPU-dense deployments, substantial capital is bound up in equipment that may leave its primary workload well before it stops working. A poorly coordinated exit converts potential returns into idle inventory.
Traceability Is Part of Value Recovery
Speed alone, however, is not a sufficient measure of an effective disposition program. AI infrastructure operates across jurisdictions, handles sensitive information and may involve hardware subject to trade controls. Li argued that financial recovery and security need not conflict when verification is built into the process.
Her model starts with serialized asset tracking and an unbroken digital chain of custody from the data center floor to the final disposition site. It extends through GPS-monitored logistics, tamper-evident handling, appropriately vetted personnel and documented processing procedures. Data-bearing devices must be sanitized or physically destroyed as required before entering reuse or recovery channels—even when their next destination is another facility operated by the same company.
Li cited recognized sanitization standards alongside local legal requirements. NIST SP 800-88, for example, provides guidance on enterprise programs for securely sanitizing media. A process acceptable in one location cannot simply be assumed to satisfy every rule governing another.
International remarketing adds trade restrictions and embargoes that can bar certain buyers or destinations. For permitted transactions, Li advocated traceability to the ultimate purchaser and use.
Processing geography therefore matters. Li described maintaining facilities in both the Netherlands and United Kingdom as a response to post-Brexit cross-border complications. Operators may choose a global partner with local processing or specialized domestic providers, depending on the market.
The governing question is whether the chosen network can move assets quickly while demonstrating where they went, how they were handled and what became of them.
Designing the AI Factory for More Than One Life
Li’s longer-term vision goes beyond managing the exit of today’s racks. She wants hardware designed from the outset for disassembly, component replacement and second or third operational uses—the extension of design-for-recycling principles into the architecture of AI computing systems.
That would mean treating modularity and recoverability as engineering requirements, not optional sustainability benefits. Equipment assembled in ways that frustrate disassembly may be fast or economical to manufacture but expensive to recover later. The same logic applies to material selection: knowing which valuable or supply-constrained inputs are built into a system is a prerequisite for recovering them efficiently.
Li raised bismuth, a critical mineral used in certain low-melting-point alloys and electronic applications, as an illustration of why the material content of infrastructure deserves closer attention. Recycling and reclamation, in this view, are also questions of future supply-chain resilience.
Procurement contracts can reinforce those design choices by specifying responsibilities for return, processing and downstream recovery. Operators would then have greater visibility not only into the acquisition cost of a GPU system, but also into the resources and residual value likely to remain when its first application is complete.
But the organizational model may be the hardest part to change. Li said the most expensive mistake is failing to establish lifecycle policy at the C-suite level. Without that direction, retirement decisions can circulate among IT, procurement, finance and legal teams as equipment sits unused and potential returns become harder to capture.
The result is what she calls “stranded capital”: money invested in productive infrastructure that is no longer producing value, yet has not been converted into another operational use or financial return.
Her parting point was that AI operators do not need to discover every failure mode themselves. Telecom network upgrades and the smartphone industry’s early race to market both offer lessons in what happens when the forward supply chain receives all the attention and the reverse supply chain is left to catch up.
“You don't have to make the mistake personally in order to learn from it,” Li said.
As the AI buildout advances, the implication is straightforward. The useful life of a GPU and its life in a frontier AI cluster are not necessarily the same thing. Operators that plan for the distinction at the design and contracting stage will be better positioned to capture the value of both.
At Data Center Frontier, we talk the industry talk and walk the industry walk. In that spirit, DCF Staff members may occasionally use AI tools to assist with content.
Keep pace with the fast-moving world of data centers and cloud computing by connecting with Data Center Frontier on LinkedIn, following us on X/Twitter and Facebook, as well as on BlueSky, and signing up for our weekly newsletters using the form below.
About the Author
 Matt Vincent
Matt Vincent is Editor in Chief of Data Center Frontier, where he leads editorial strategy and coverage focused on the infrastructure powering cloud computing, artificial intelligence, and the digital economy. A veteran B2B technology journalist with more than two decades of experience, Vincent specializes in the intersection of data centers, power, cooling, and emerging AI-era infrastructure. Since assuming the EIC role in 2023, he has helped guide Data Center Frontier’s coverage of the industry’s transition into the gigawatt-scale AI era, with a focus on hyperscale development, behind-the-meter power strategies, liquid cooling architectures, and the evolving energy demands of high-density compute, while working closely with the Digital Infrastructure Group at Endeavor Business Media to expand the brand’s analytical and multimedia footprint. Vincent also hosts The Data Center Frontier Show podcast, where he interviews industry leaders across hyperscale, colocation, utilities, and the data center supply chain to examine the technologies and business models reshaping digital infrastructure. Since its inception he serves as Head of Content for the Data Center Frontier Trends Summit. Before becoming Editor in Chief, he served in multiple senior editorial roles across Endeavor Business Media’s digital infrastructure portfolio, with coverage spanning data centers and hyperscale infrastructure, structured cabling and networking, telecom and datacom, IP physical security, and wireless and Pro AV markets. He began his career in 2005 within PennWell’s Advanced Technology Division and later held senior editorial positions supporting brands such as Cabling Installation & Maintenance, Lightwave Online, Broadband Technology Report, and Smart Buildings Technology. Vincent is a frequent moderator, interviewer, and keynote speaker at industry events including the HPC Forum, where he delivers forward-looking analysis on how AI and high-performance computing are reshaping digital infrastructure. He graduated with honors from Indiana University Bloomington with a B.A. in English Literature and Creative Writing and lives in southern New Hampshire with his family, remaining an active musician in his spare time.
Voices of the Industry
 Adobe Stock image courtesy of Hitachi Energy