NVIDIA's DSX POD Pushes AI Factory Construction Toward the Assembly Line
Key Highlights
- NVIDIA's DSX POD reference design aims to industrialize AI factory construction, integrating Vera Rubin computing, networking, power and liquid cooling into factory-built modular containers designed for deployment at prepared sites in as little as 14 days.
- A growing partner ecosystem is bringing scale to the modular AI infrastructure movement, with Armada and Johnson Controls targeting 500 MW of distributed capacity in 2027, alongside manufacturing initiatives from Crusoe, Schneider Electric and major OEMs.
- Prefabrication is demonstrating measurable installation advantages. A Schneider Electric–Compass Datacenters study found an 80% reduction in onsite installation time for prefabricated white-space modules, while Vertiv models nearly 30% greater first-year cumulative AI token output through accelerated deployment.
- DSX POD extends NVIDIA's broader DSX AI Factory architecture into physical manufacturing, building on the company's 2026 initiatives in infrastructure simulation, power optimization and behind-the-meter energy integration.
- Power availability and supply chain constraints remain the ultimate tests. NVIDIA's 14-day deployment vision depends on prepared sites, reliable component supplies and energy infrastructure that can take years to deliver, raising questions about how quickly industrialized AI factories can scale.
NVIDIA is making a new push to change how AI data centers are built, introducing a factory-integrated infrastructure model intended to move much of the complex work of assembling, connecting and validating high-density computing systems away from construction sites and into manufacturing facilities.
Unveiled October 21 at GTC Berlin, the company's new DSX POD reference design is designed around the NVIDIA Vera Rubin platform and packages computing, networking, rack-level power and liquid cooling inside standardized modular containers. Rather than bringing those systems together through successive stages of onsite installation, participating manufacturers would complete integration, cabling, piping and functional testing before shipment.
NVIDIA claims the approach could reduce deployment time at a suitably prepared site from six months to as little as 14 days, allowing operators to begin generating production AI tokens and earning revenue substantially sooner. A global partner ecosystem is preparing to deliver the systems beginning in early 2027.
"An AI factory creates value when it starts producing tokens — not when construction is complete," said NVIDIA founder and CEO Jensen Huang.
The announcement arrives as operators face mounting pressure to bring increasingly power-dense AI infrastructure online while managing skilled labor shortages, long construction schedules and rapidly changing hardware requirements.
But the larger development is not simply NVIDIA's two-week deployment target. Separate announcements from its infrastructure partners reveal an increasingly substantial industrial base taking shape around standardized, factory-manufactured AI capacity.
From Crusoe's new modular manufacturing facility in Colorado to Schneider Electric's expanding prefabrication capacity, Armada's proposed 500 MW sovereign AI infrastructure program and Vertiv's work on a 41 MW deployment in Norway, the common objective is to make AI infrastructure delivery more repeatable, predictable and less dependent on assembling every system from scratch in the field.
Modular construction has been one of the defining trends of the AI data center buildout, as developers look for ways to accelerate deployment while managing increasingly complex, power-dense infrastructure. What makes NVIDIA's DSX POD announcement potentially consequential is the scale of the proposed standardization. The ambition is no longer simply to manufacture electrical rooms, cooling systems or other infrastructure components offsite, but to deliver the AI factory itself as a repeatable, factory-integrated product.
The emerging model does not eliminate the need for conventional data center development. It does, however, propose a significant reorganization of where—and when—the most intricate infrastructure integration work gets done.
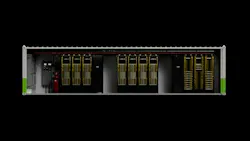
NVIDIA outlines how its DSX platform integrates computing, power, cooling and infrastructure simulation, with DSX POD extending the architecture into factory-built, containerized AI factories. (Source: NVIDIA)
From the DSX AI Factory Blueprint to DSX POD
The underlying engineering proposition is straightforward: as AI computing becomes more complex, particularly with the adoption of rack-scale liquid-cooled architectures, traditional methods of assembling and integrating equipment onsite introduce scheduling risks that become increasingly consequential.
Electrical infrastructure, cooling distribution, networking, racks and compute hardware must operate as an integrated system. Delays or design changes in one discipline can affect multiple others.
DSX POD is intended to address that coordination problem by establishing a repeatable, validated architecture that manufacturers can assemble and test in controlled environments while site preparation proceeds separately.
Importantly, DSX POD is distinct from NVIDIA's broader Vera Rubin DSX AI Factory reference design, introduced in March. That design provides a facility-wide architectural framework encompassing compute, networking, storage, electrical distribution, cooling, controls and the engineering systems required to operate an AI factory. The larger DSX platform also incorporates simulation, infrastructure orchestration and software for optimizing computing output within available power budgets.
NVIDIA's recently introduced DSX Ready qualification program extends that standardization effort to battery energy storage and liquid-cooling equipment, establishing technical requirements for the infrastructure supporting AI computing.
DSX POD translates those principles into a specific physical delivery model: containerized Vera Rubin AI factories assembled, integrated and validated offsite, then connected to prepared power, cooling and networking infrastructure. It is an extension of the broader DSX architecture, not a replacement for the site and facility systems that support it.
The company's partner roster includes Dell Technologies, HPE, Lenovo, Bull, Foxconn/Ingrasys, Quanta Cloud Technology, Wistron, Pegatron, GIGABYTE, Schneider Electric, Vertiv, Eaton, Delta, Crusoe, Armada, DayOne and Anduril.
The breadth of that ecosystem is central to the strategy. Bringing a complete AI factory into production requires much more than shipping GPUs. It requires manufacturers capable of standardizing the electrical, thermal, structural and computing interfaces surrounding those systems.
Armada and Johnson Controls Target 500 MW of Distributed AI Capacity
One of the most ambitious announcements accompanying the NVIDIA launch came from Armada, which disclosed plans to work with Johnson Controls on a distributed sovereign AI infrastructure program targeting 500 MW of capacity in 2027.
Under the announced collaboration, Armada and Johnson Controls intend to engineer, manufacture and integrate modular AI factories based on Vera Rubin and the DSX POD reference design, with much of the wiring, piping, cabling and functional validation completed before the systems leave the factory.
Manufacturing is expected to draw on Armada's Galleon Forge facilities in Gilbert, Arizona, and Dublin, Ireland, supported by Johnson Controls' thermal management expertise and manufacturing capabilities.
Armada also plans to use NVIDIA DSX Air for simulation and predeployment validation and DSX MaxLPS to optimize AI computing output within available power limits once installations are operating.
"The SI race isn't going to be won by whoever pours concrete the fastest," said Dan Wright, Armada's co-founder and CEO.
Armada's approach emphasizes geographically distributed facilities located near available energy resources, rather than concentrating all capacity in a small number of enormous campuses. The company sees applications for sovereign AI computing, latency-sensitive workloads and deployments where energy availability or local infrastructure conditions favor smaller installations.
The proposed 500 MW program remains a forward-looking development target, not an accounting of installed or contracted DSX POD capacity. Nevertheless, its scale illustrates how vendors envision factory-integrated infrastructure becoming more than a niche solution for edge computing.
The model is straightforward in concept: standardize the computing infrastructure, manufacture it in volume and distribute deployments across locations where the necessary power and connectivity can be secured.
Schneider Electric and Compass Put Numbers Behind Prefabrication
While NVIDIA's two-week deployment target remains to be demonstrated at commercial scale, Schneider Electric has released more concrete evidence of the potential labor and installation savings associated with prefabricated infrastructure.
At GTC Berlin, Schneider introduced its RapidScale Modular Data Center Reference Design 115, a high-density architecture supporting the NVIDIA Vera Rubin platform and integrating power, liquid cooling, IT infrastructure and lifecycle services.
The company describes the design as an initial step toward supporting DSX POD, rather than a completed deployment of the NVIDIA containerized architecture.
More significant from an operational standpoint is a time study jointly developed with Compass Datacenters, examining the installation work that can be eliminated when high-density white-space infrastructure is assembled and tested before arriving at the data center.
The study compared a conventional installation sequence with prefabricated IT pods incorporating power distribution, cooling piping, containment and cable pathways. Conventionally, those systems require separate onsite installation activities, often involving multiple specialized trades working within the same constrained space.
At a Compass hyperscale campus, moving those activities into factory assembly reduced the measured onsite installation time from 75.5 hours using conventional methods to approximately 15 hours per prefabricated pod—an 80% reduction.
The savings came primarily from eliminating or consolidating field activities, rather than crews performing the same work faster. The study also documented improvements through repetition, with installation time declining from 18 hours to 15 hours as crews gained experience.
Those figures do not represent an 80% reduction in total data center construction time. They measure a specific portion of the installation process. Still, the findings offer useful evidence that factory integration can materially reduce the coordination demands and labor requirements of high-density construction.
Manufacturing scale is another part of Schneider's argument.
The company reports that its modular infrastructure manufacturing capacity has increased fourfold since 2025. Its primary manufacturing footprint now encompasses eight sites totaling approximately 1.35 million square feet, supplemented by three additional company facilities and 12 partner sites across 10 countries.
Schneider says its RapidScale solutions incorporate approximately 90% internally manufactured equipment, positioning the company to manage a larger share of the infrastructure supply chain directly.
These investments suggest that prefabrication is evolving from an alternative construction method into a core manufacturing strategy for large AI infrastructure suppliers.
Crusoe introduces Spark Liquid, its next-generation modular AI factory designed for high-density, liquid-cooled computing. The platform illustrates the established manufacturing approach NVIDIA aims to standardize through DSX POD. (Source: Crusoe)
Crusoe Brings an Established Modular Model to DSX POD
For Crusoe, NVIDIA's announcement builds on a modular computing strategy already in operation.
In its October 21 announcement, Crusoe confirmed that its Spark modular AI data center platform will support DSX POD, extending a manufacturing and deployment approach the company says it has pursued since 2020.
Crusoe has expanded its manufacturing capabilities through the acquisition of electrical equipment specialist Easter-Owens Electric and the development of its 352,000-square-foot Crusoe Spark Factory in Brighton, Colorado.
The company also introduced Crusoe Spark Liquid, a sixth-generation modular system engineered for ultra-high-density infrastructure, including NVIDIA Vera Rubin NVL72. Next-generation liquid-cooled units are planned for 2027.
Crusoe's vertically integrated model connects infrastructure design and manufacturing with deployment and cloud operations through Crusoe Cloud. The company says it can deliver productive AI capacity in as little as three months, although that timeline is distinct from NVIDIA's narrower 14-day prepared-site deployment claim.
"Modular isn't a new strategy or pivot for us. It's been in our DNA since our founding," said Bryan Schramm, Crusoe's head of Spark.
Crusoe's involvement demonstrates that the manufacturing model predates DSX POD. NVIDIA is not inventing modular data center infrastructure; it is attempting to establish a common architecture around capabilities that suppliers such as Crusoe have already spent years developing.
That distinction matters as the industry evaluates whether standardized AI factory designs can deliver manufacturing efficiencies at a scale beyond individual suppliers' existing operations.
Vertiv and Polar Put the Deployment Model to Work in Norway
The European dimension of NVIDIA's announcement is reflected in a deployment involving Vertiv and Polar Data Centers at Herøya, Norway.
According to Vertiv's October 21 announcement, Polar is applying a factory-built infrastructure approach to the initial 41 MW phase of a multiphase AI data center campus designed to scale to 100 MW.
Vertiv is supplying prefabricated power and thermal infrastructure, including SmartRun overhead systems and SmartMod modules, supported by its Unify software.
The project applies principles of the broader NVIDIA DSX AI Factory reference design, rather than representing a confirmed installation of a complete DSX POD container. Even so, it offers a practical example of pre-engineered infrastructure being deployed at scale.
Vertiv has also published a model quantifying the potential economic advantage of shortening AI factory delivery.
The company's argument starts with a distinction between the performance of installed computing equipment and the productive time available to use it. Two AI factories equipped with identical hardware may generate tokens at the same daily rate, but the facility that becomes operational earlier can produce substantially more cumulative output during its first year.
Under Vertiv's modeled assumptions, standardized design and virtual validation reduce the configuration stage from approximately 30 days to three days. Factory-built infrastructure then cuts the modeled deployment period from 90 days to 45 days.
Together, those improvements compress the relevant engineering and deployment stages from roughly 120 days to 48 days, bringing productive AI capacity online approximately 10 weeks sooner.
Over the first year following project kickoff, that translates to 317 productive days rather than 245. Assuming identical installed computing capacity and daily production rates, Vertiv projects the accelerated approach could yield nearly 30% more cumulative AI token output during that period.
The calculation is a modeled comparison, not a claim of faster GPU performance or a measured throughput improvement at Polar. The projected advantage comes from putting the same expensive computing infrastructure into productive service sooner.
"An AI factory earns its return in tokens," said Vertiv CEO Giordano Albertazzi.
The economic argument reflects a growing emphasis on time to first token as a measure of infrastructure delivery performance. For operators committing substantial capital to next-generation GPUs, months spent waiting for systems to become productive carry a potentially significant opportunity cost.
Virtual Twins Extend the Factory Model Into Engineering
Factory integration is only one part of the proposed transformation. Suppliers are also attempting to standardize the engineering and validation processes that precede manufacturing.
On October 22, Dassault Systèmes and Vertiv announced a collaboration to use Dassault's 3DEXPERIENCE platform and virtual-twin technology to configure, simulate and validate AI factory infrastructure before construction.
The companies are combining Vertiv's pre-engineered power and cooling systems with NVIDIA's DSX AI Factory reference designs and Omniverse DSX Blueprint.
The objective is to model interconnected computing, electrical, thermal, networking and control systems within a common engineering environment, allowing changes in equipment configuration or operating requirements to be evaluated before they become field installation problems.
The collaboration extends work involving Vertiv's SmartRun configurable virtual twin to broader infrastructure offerings, including its OneCore integrated data center platform.
The larger implication is that industrialized AI infrastructure requires more than standardized equipment. It also requires repeatable methods of configuring, testing and modifying interconnected systems for different sites, preserving design integrity from manufacturing through commissioning and subsequent technology upgrades.
An Expanding OEM and Operator Ecosystem
Other NVIDIA partners are developing complementary approaches to factory-integrated AI infrastructure.
Dell Technologies has announced the Dell Modular Data Center with NVIDIA DSX POD, a containerized offering intended to integrate computing, storage, networking, rack-level power and liquid cooling. The company targets availability of its modular DSX reference design in early 2027.
HPE likewise plans to support DSX POD through its existing AI Mod Pod modular infrastructure capabilities.
Meanwhile, Singapore-based DayOne Data Centers is aligning its standardized construction and modular delivery approach with DSX POD. DayOne reports that its prefabrication strategy can support data center project delivery in approximately eight to twelve months in Southeast Asia.
That broader construction timeline provides useful context for NVIDIA's much shorter prepared-site deployment target. Even when computing systems arrive as tested modular assemblies, the surrounding infrastructure and site development remain substantial undertakings.
Taken together, the announcements suggest an emerging ecosystem in which equipment manufacturers, mechanical and electrical infrastructure suppliers, modular data center builders and operators can coordinate around more consistent engineering and integration requirements.
DSX POD also brings into focus the progression of NVIDIA's announcements throughout 2026. At GTC in March, Huang declared that the "inference inflection" had arrived, as reasoning models and emerging agentic workloads drove a new phase of computing demand. NVIDIA introduced its Vera Rubin DSX AI Factory reference design that month, then expanded the DSX platform in May into a broader framework spanning infrastructure design, operations and token economics.
Now, with DSX POD, that increasingly integrated architecture extends into the manufacturing and physical delivery of the AI factory itself. What began as a story about accelerating demand for inference is becoming a story about industrializing the infrastructure required to deliver it.
What the Factory Model Changes—and What It Doesn't
There are important limits to the industrialization narrative.
NVIDIA's 14-day deployment claim applies to a prepared site. It does not mean a greenfield AI data center can move from land acquisition to commercial operation in two weeks.
Nor does factory integration eliminate every supply chain constraint. Manufacturing complete AI systems requires dependable access to GPUs, networking equipment, electrical components, cooling systems and skilled production labor.
Some complexity is reduced at the construction site; other complexity moves upstream into manufacturing, logistics, system validation and production planning.
The industry must also demonstrate that standardized containers can accommodate successive generations of computing hardware without sacrificing the flexibility operators need for service, maintenance and upgrades.
For now, the evidence supporting industrialized deployment comes from several different sources: measured installation improvements such as the Schneider Electric-Compass study, existing modular manufacturing operations such as Crusoe's, real-world projects applying broader DSX principles such as Polar's Norway campus, and forward-looking programs such as Armada's 500 MW initiative.
Those developments provide a basis for evaluating the emerging manufacturing model, but they are not yet proof that every benefit attributed to DSX POD has been achieved at commercial scale.
Ultimately, NVIDIA's vision of a 14-day deployment remains tethered to the realities of heavy infrastructure. Securing high-voltage grid connections, substations and necessary transmission upgrades can take years, long before a site is ready to receive its first DSX POD. NVIDIA is already reaching upstream into that problem. As Data Center Frontier reported in September, its broader DSX strategy encompasses powered-land development and behind-the-meter generation, with DSX Flex designed to coordinate grid power, onsite resources and computing demand.
But neither behind-the-meter power nor factory integration eliminates infrastructure dependencies; they reorganize them. Onsite generation brings its own permitting, equipment and fuel-supply challenges, while moving integration upstream creates new dependencies on standardized components and tightly coordinated manufacturing schedules. A shortage of cooling equipment or optical transceivers could disrupt delivery of otherwise completed AI factory modules.
The ultimate test is therefore not simply whether NVIDIA can deploy an AI factory in 14 days. It is whether the power infrastructure and industrial supply chains supporting that deployment can keep pace with the speed of silicon.
At Data Center Frontier, we talk the industry talk and walk the industry walk. In that spirit, DCF Staff members may occasionally use AI tools to assist with content.
Keep pace with the fast-moving world of data centers and cloud computing by connecting with Data Center Frontier on LinkedIn, following us on X/Twitter and Facebook, as well as on BlueSky, and signing up for our weekly newsletters using the form below.
About the Author
 Matt Vincent
Matt Vincent is Editor in Chief of Data Center Frontier, where he leads editorial strategy and coverage focused on the infrastructure powering cloud computing, artificial intelligence, and the digital economy. A veteran B2B technology journalist with more than two decades of experience, Vincent specializes in the intersection of data centers, power, cooling, and emerging AI-era infrastructure. Since assuming the EIC role in 2023, he has helped guide Data Center Frontier’s coverage of the industry’s transition into the gigawatt-scale AI era, with a focus on hyperscale development, behind-the-meter power strategies, liquid cooling architectures, and the evolving energy demands of high-density compute, while working closely with the Digital Infrastructure Group at Endeavor Business Media to expand the brand’s analytical and multimedia footprint. Vincent also hosts The Data Center Frontier Show podcast, where he interviews industry leaders across hyperscale, colocation, utilities, and the data center supply chain to examine the technologies and business models reshaping digital infrastructure. Since its inception he serves as Head of Content for the Data Center Frontier Trends Summit. Before becoming Editor in Chief, he served in multiple senior editorial roles across Endeavor Business Media’s digital infrastructure portfolio, with coverage spanning data centers and hyperscale infrastructure, structured cabling and networking, telecom and datacom, IP physical security, and wireless and Pro AV markets. He began his career in 2005 within PennWell’s Advanced Technology Division and later held senior editorial positions supporting brands such as Cabling Installation & Maintenance, Lightwave Online, Broadband Technology Report, and Smart Buildings Technology. Vincent is a frequent moderator, interviewer, and keynote speaker at industry events including the HPC Forum, where he delivers forward-looking analysis on how AI and high-performance computing are reshaping digital infrastructure. He graduated with honors from Indiana University Bloomington with a B.A. in English Literature and Creative Writing and lives in southern New Hampshire with his family, remaining an active musician in his spare time.
Voices of the Industry
 Source: Shutterstock, courtesy of nVent Data Solutions